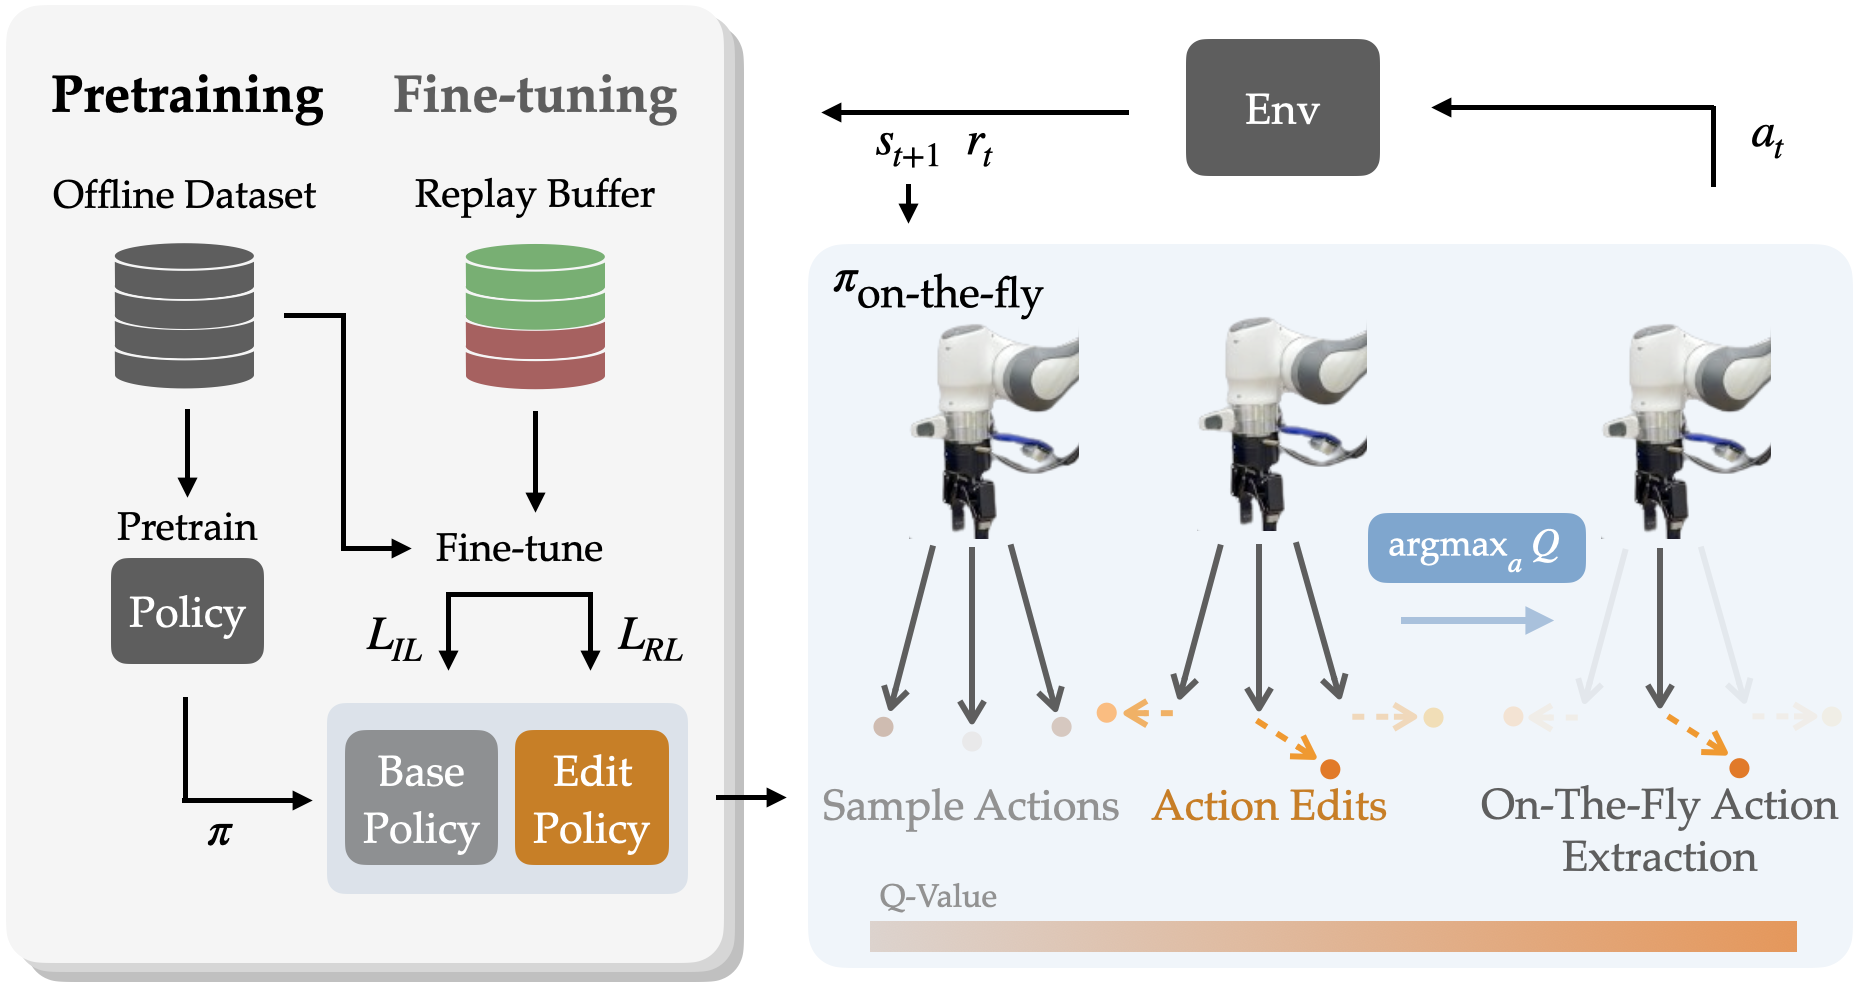
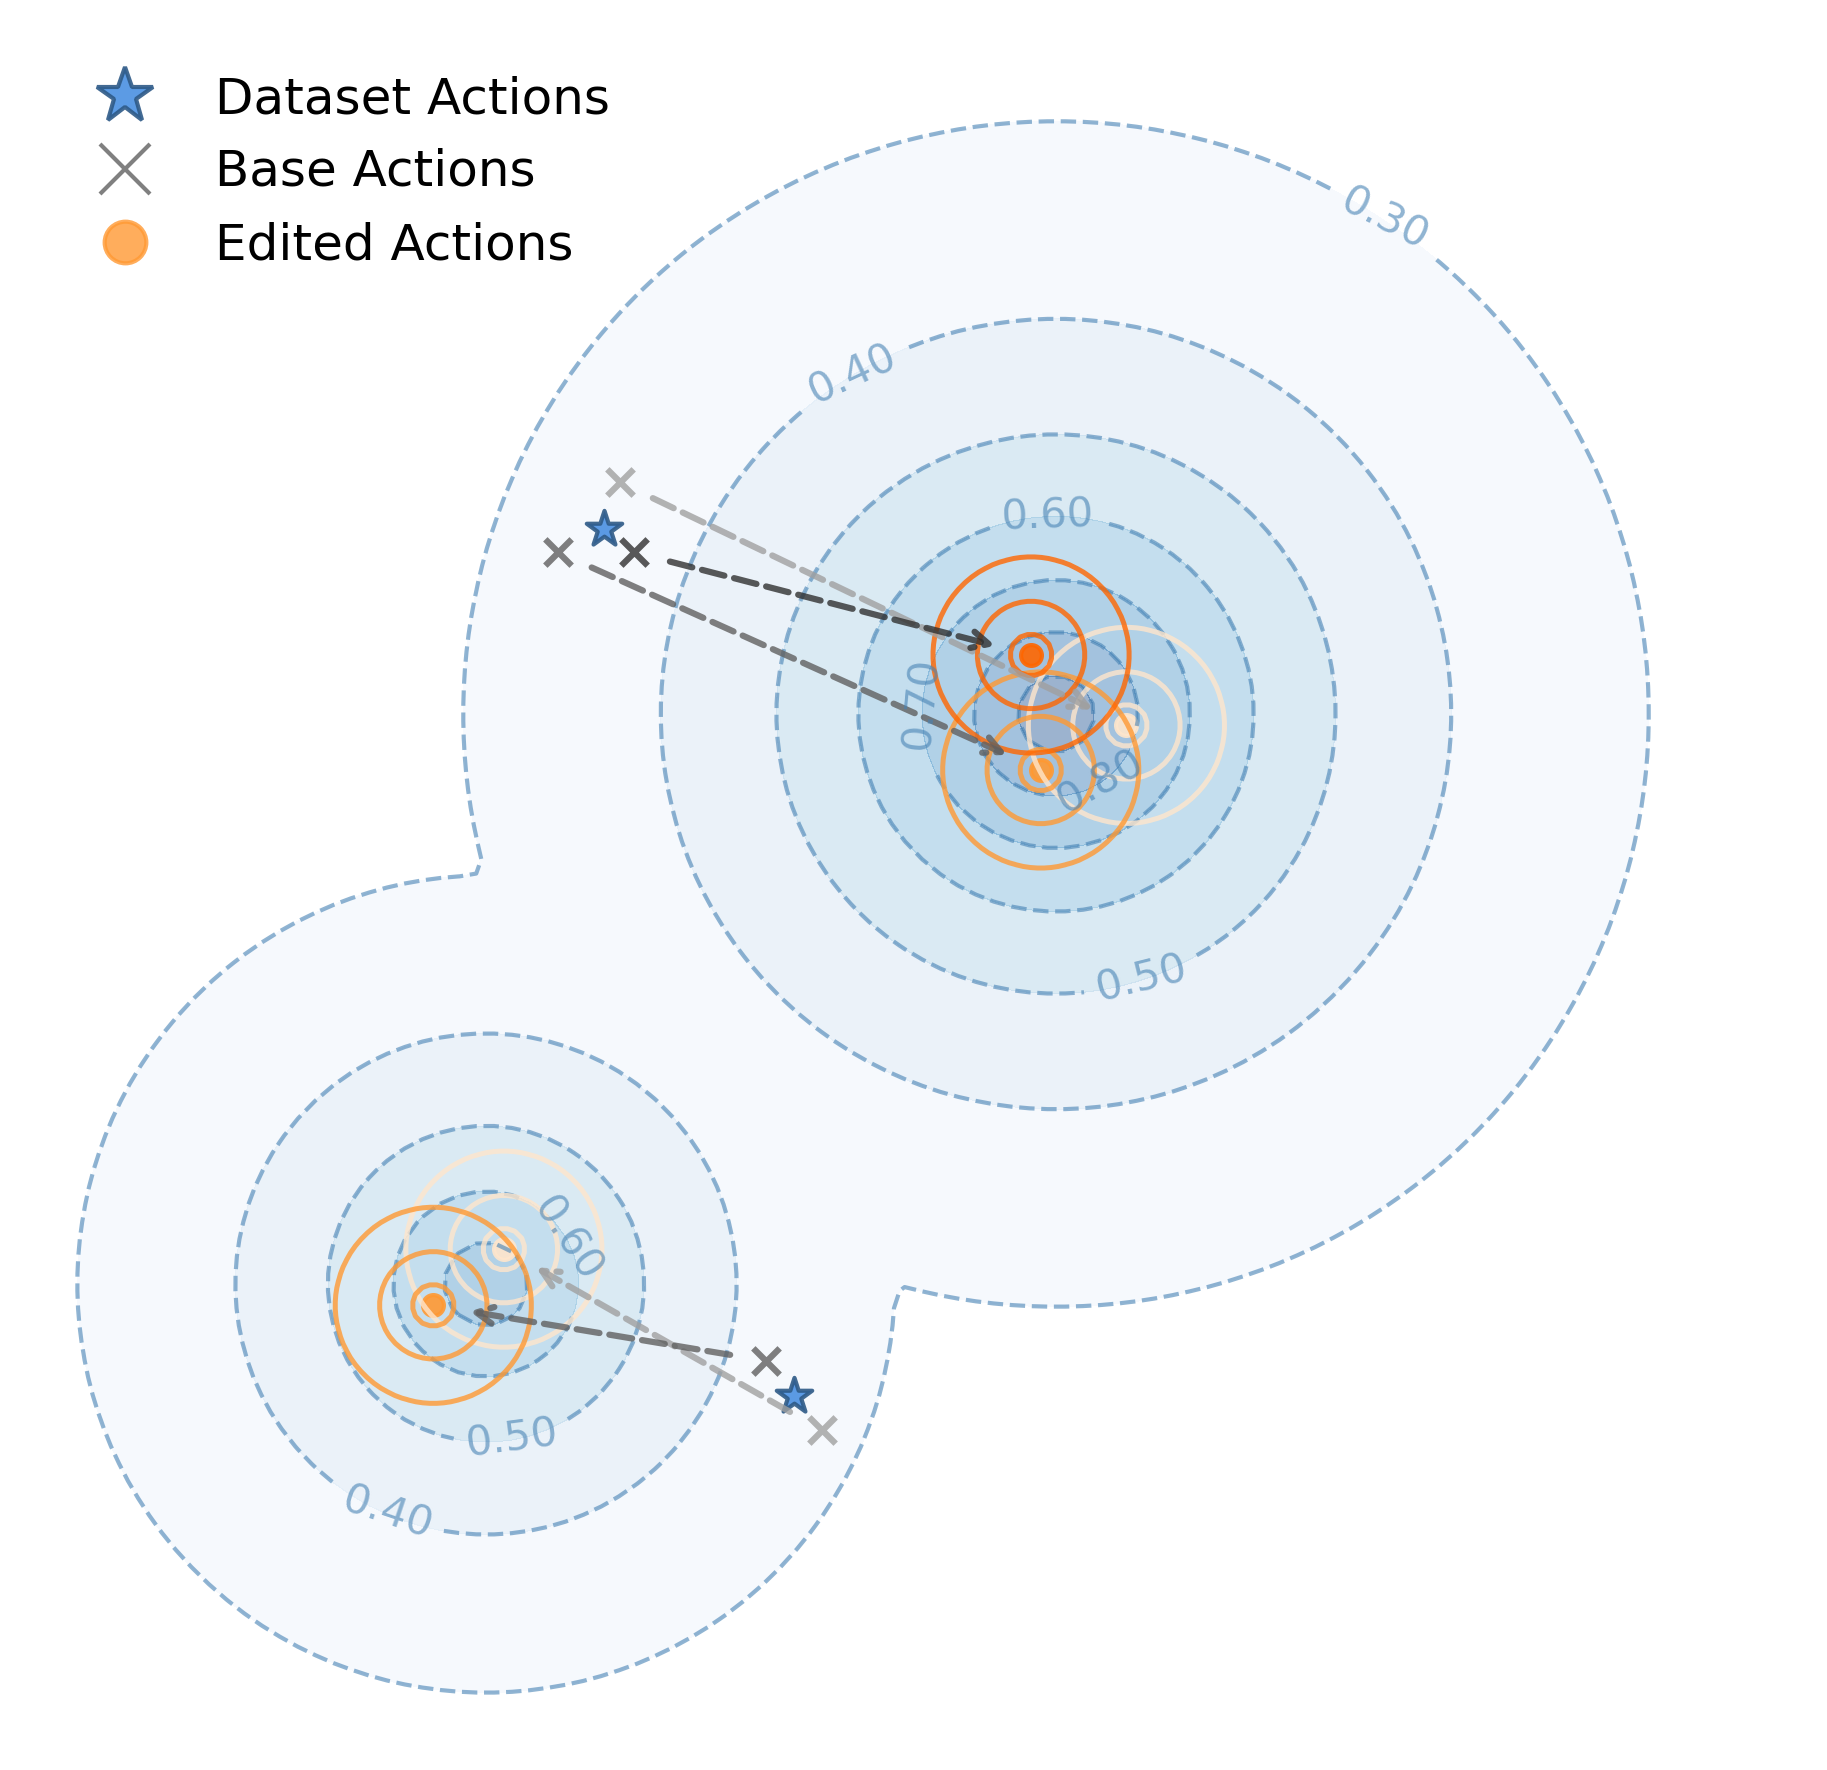
We study the problem of training and fine-tuning expressive policies with online reinforcement learning (RL) given an offline dataset. Training expressive policy classes with online RL present a unique challenge of stable value maximization. Unlike simpler Gaussian policies commonly used in online RL, expressive policies like diffusion and flow-matching policies are parameterized by a long denoising chain, which hinders stable gradient propagation from actions to policy parameters when optimizing against some value function. Our key insight is that we can address stable value maximization by avoiding direct optimization over value with the expressive policy and instead construct an on-the-fly RL policy to maximize Q-value. We propose Expressive Policy Optimization (EXPO), a sample-efficient online RL algorithm that utilizes an on-the-fly policy to maximize value with two parameterized policies -- a larger expressive base policy trained with a stable imitation learning objective and a light-weight Gaussian edit policy that edits the actions sampled from the base policy toward a higher value distribution. The on-the-fly policy optimizes the actions from the base policy with the learned edit policy and chooses the value maximizing action from the base and edited actions for both sampling and temporal-difference (TD) backup. Our approach yields up to 2-3x improvement in sample efficiency on average over prior methods both in the setting of fine-tuning a pretrained policy given offline data and in leveraging offline data to train online.
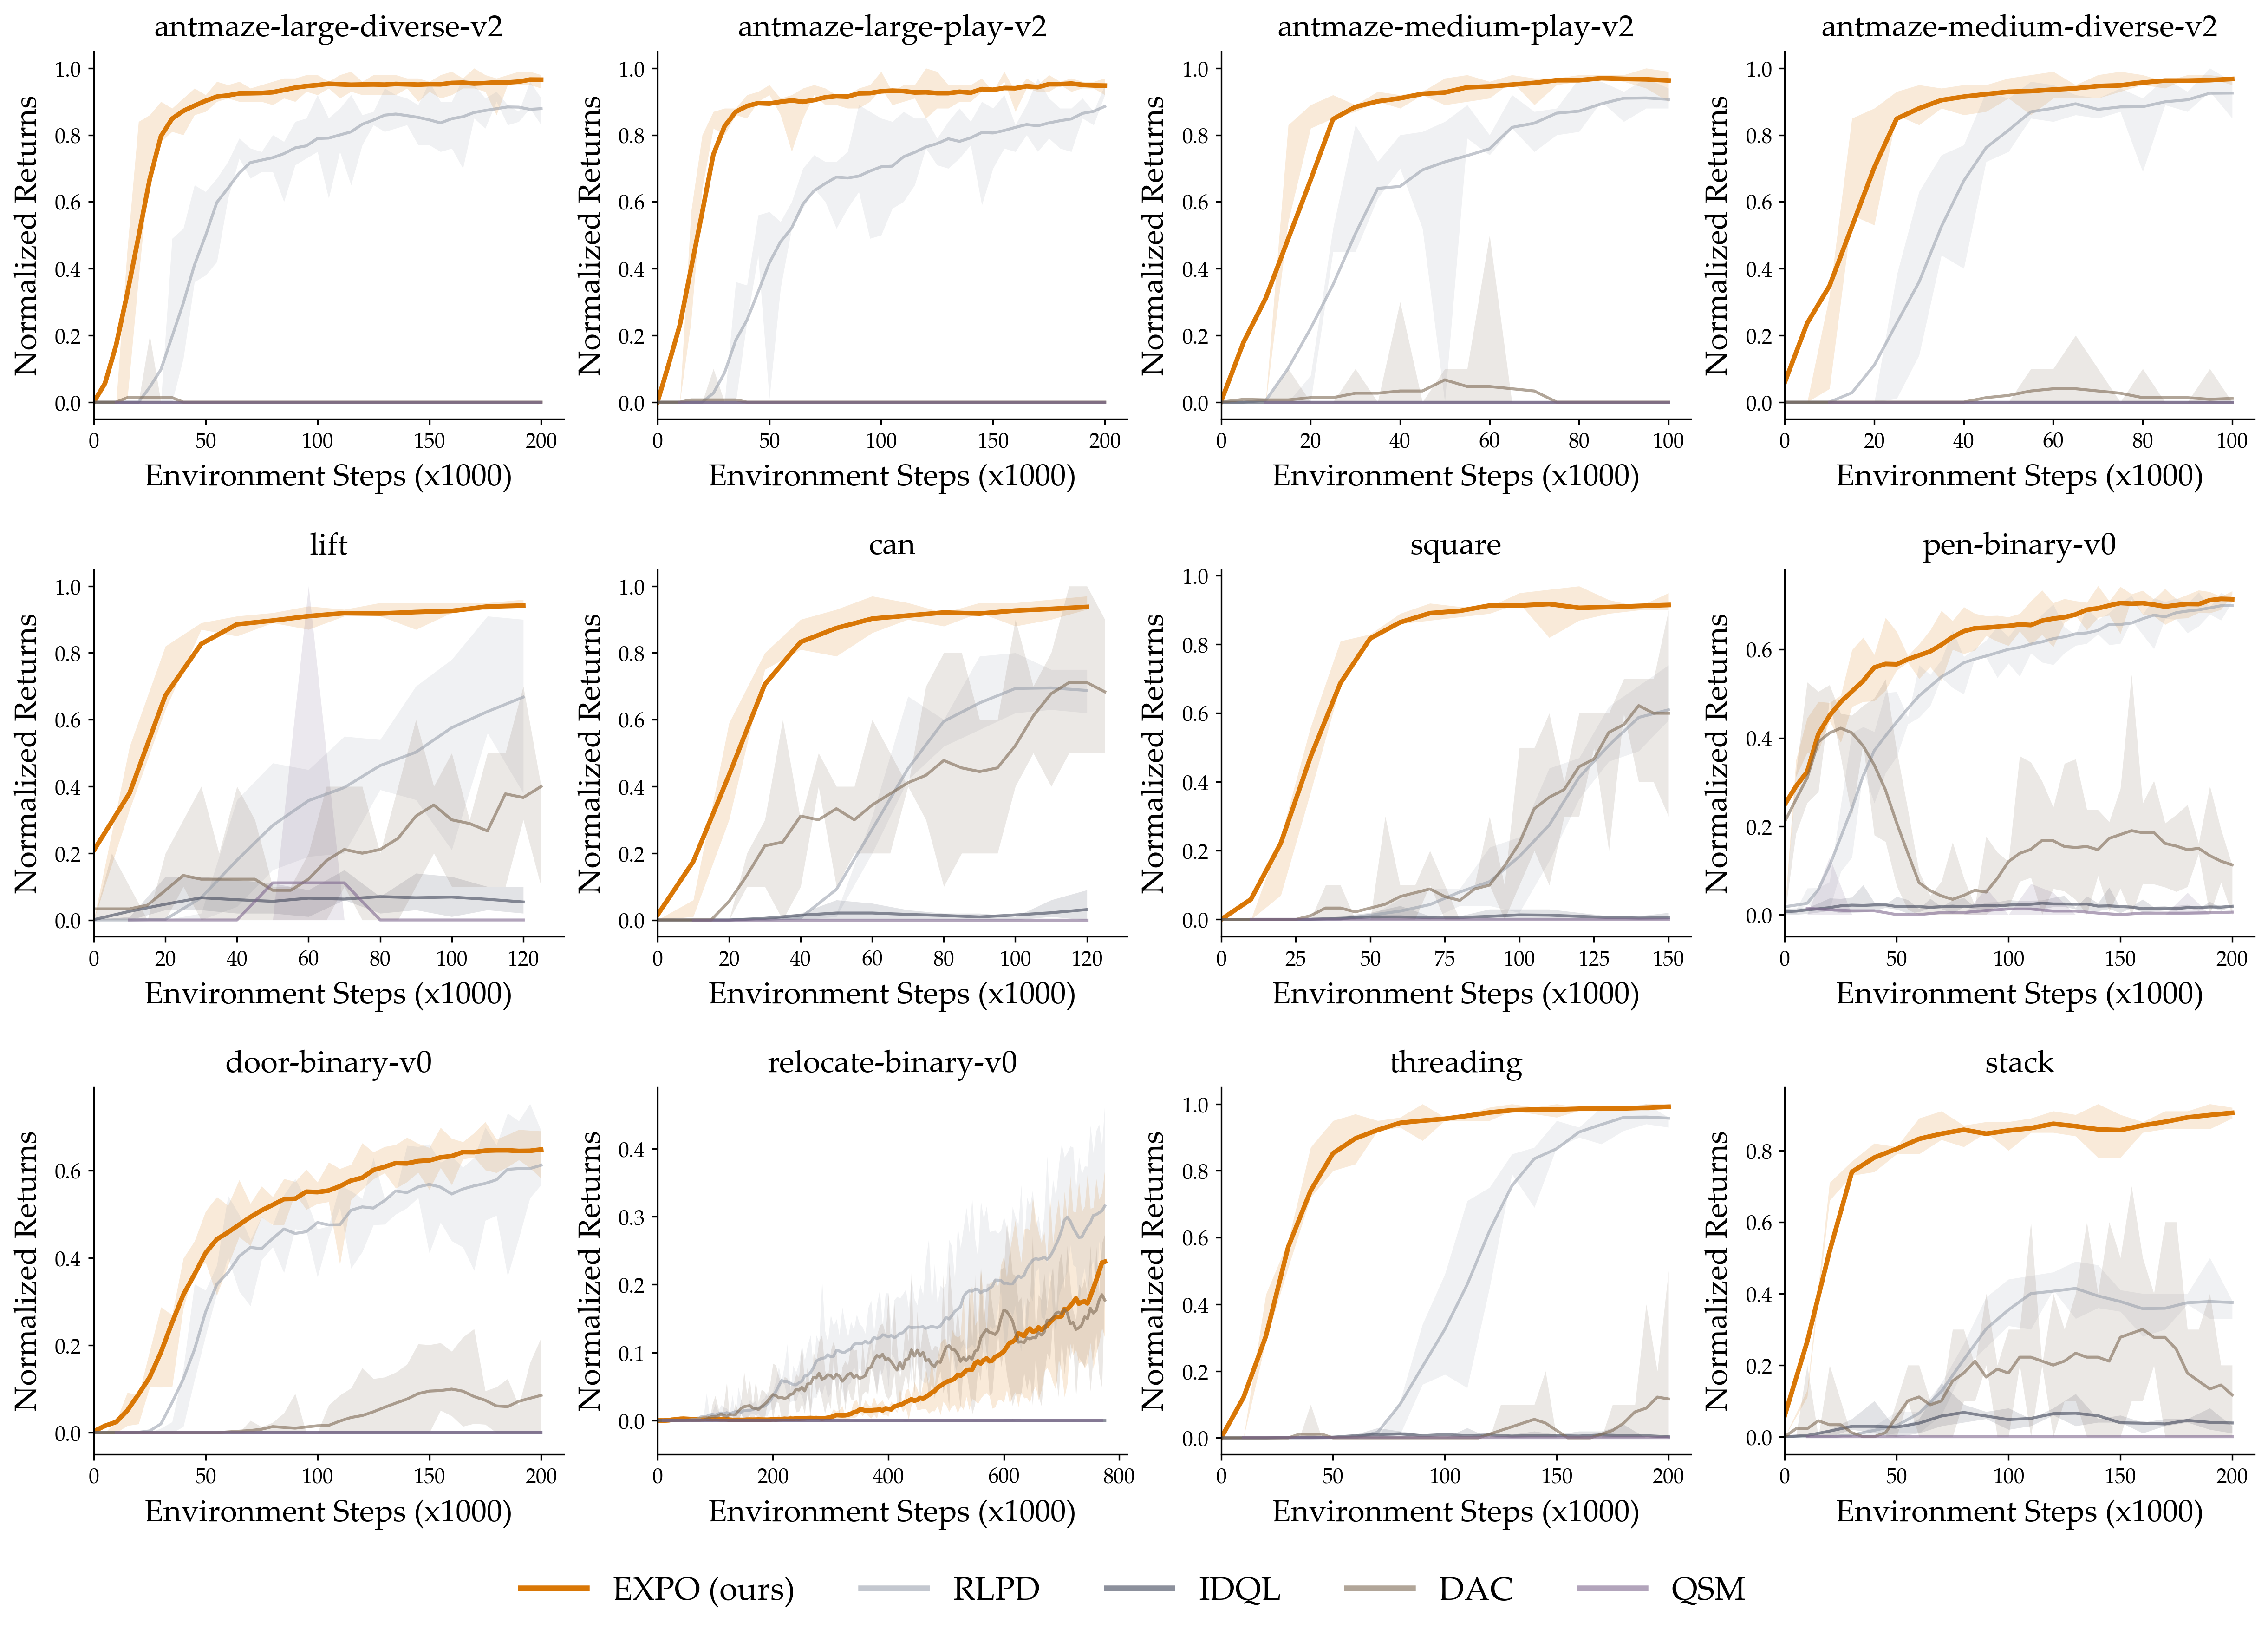
Online RL (No Pre-training). Online RL results on 12 challenging sparse-reward tasks. Across almost every task, EXPO consistently exceeds or matches the performance of the best baseline—even without any pretraining.
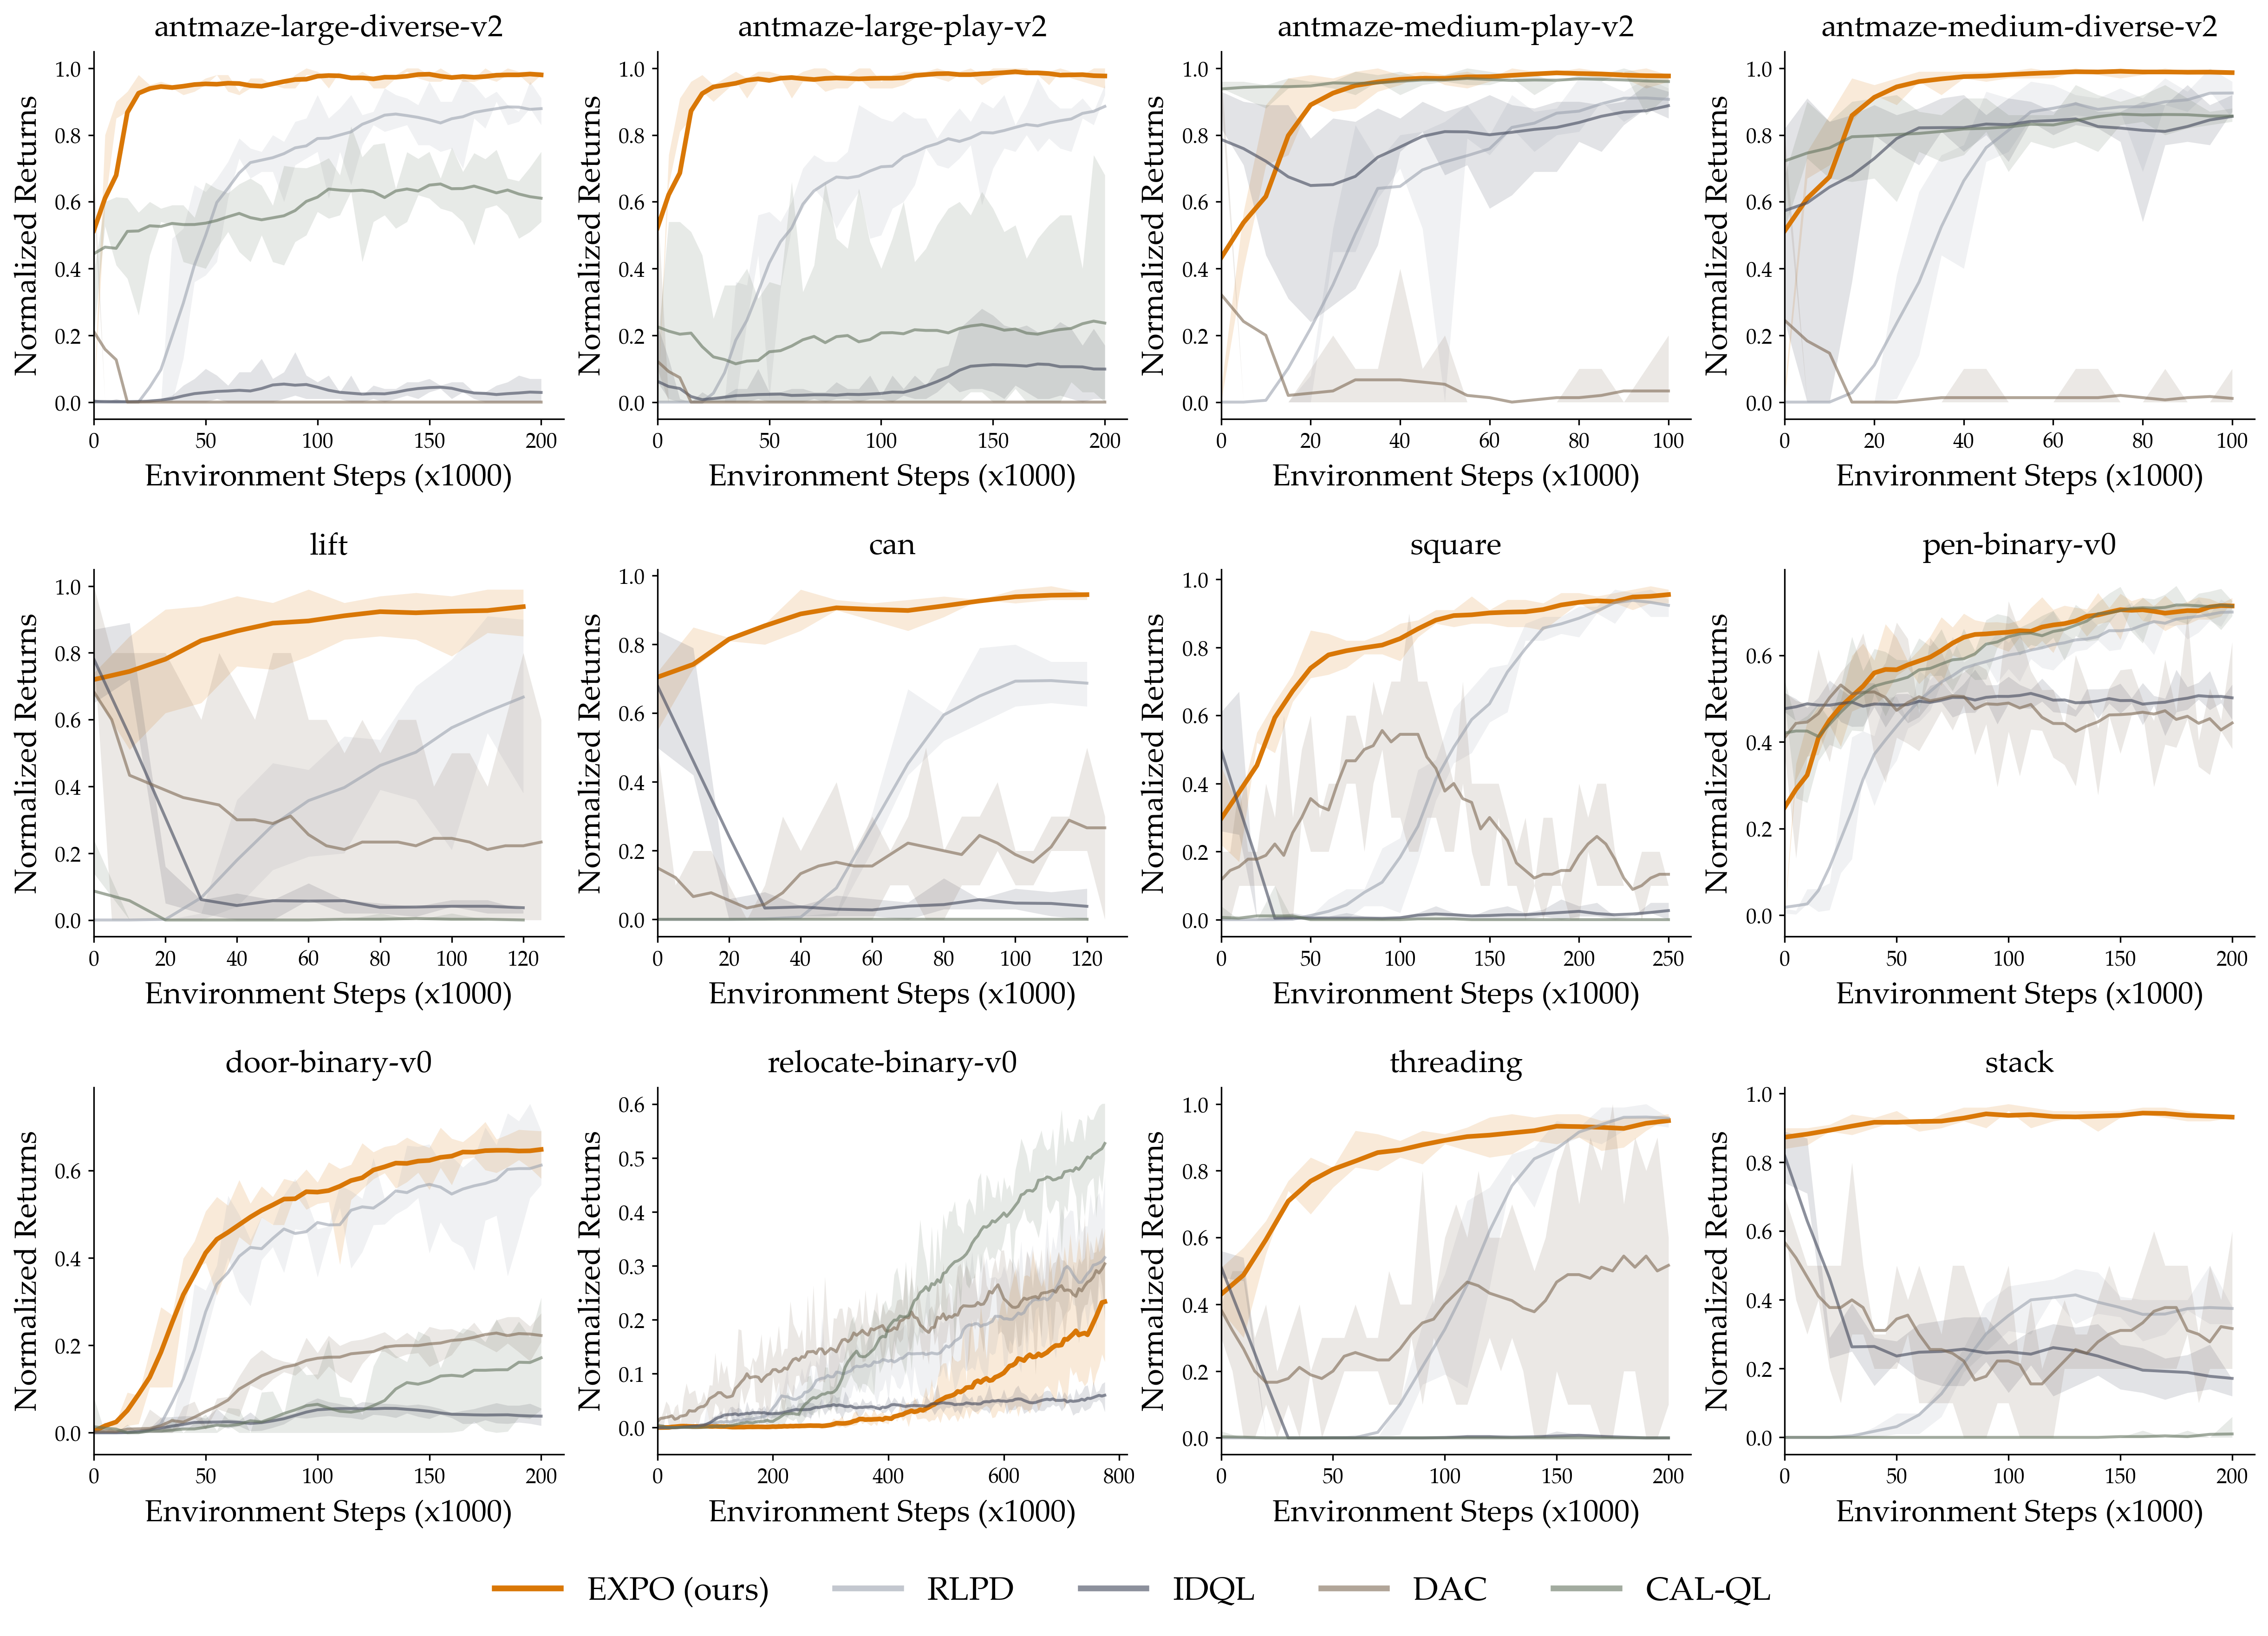
Offline-to-Online RL (Offline Pre-training Followed by Online Fine-tuning). Offline-to-online RL results on 12 challenging sparse-reward tasks. EXPO consistently exceeds or matches the performance of the best baseline. The relative benefit of EXPO over baselines is especially large on the manipulation tasks, where prior methods often struggle to improve in performance. Importantly, EXPO does not drop in performance going from pre-training to fine-tuning.
@article{dong2025expo,
    title   = {EXPO: Stable Reinforcement Learning with Expressive Policies},
    author  = {Perry Dong and Qiyang Li and Dorsa Sadigh and Chelsea Finn},
    journal = {arXiv},
    year    = {2025},
}