Perry Dong Blog (coming soon)

Computer Science PhD, Stanford University

I am a PhD student in the Department of Computer Science at Stanford University, advised by Chelsea Finn and Dorsa Sadigh. I am currently also working at Google DeepMind. My research focuses on reinforcement learning. Prior to Stanford, I received my B.S. and M.S. from UC Berkeley, working with Sergey Levine and Yi Ma.

Profile photo

Selected Publications

Real-Time EXPO-FT figure

Reinforcement Learning for Real-Time Vision-Language-Action Policies

P. Dong, K. Hung, D. Sadigh, C. Finn

arXiv preprint arXiv:2609.18207, 2026

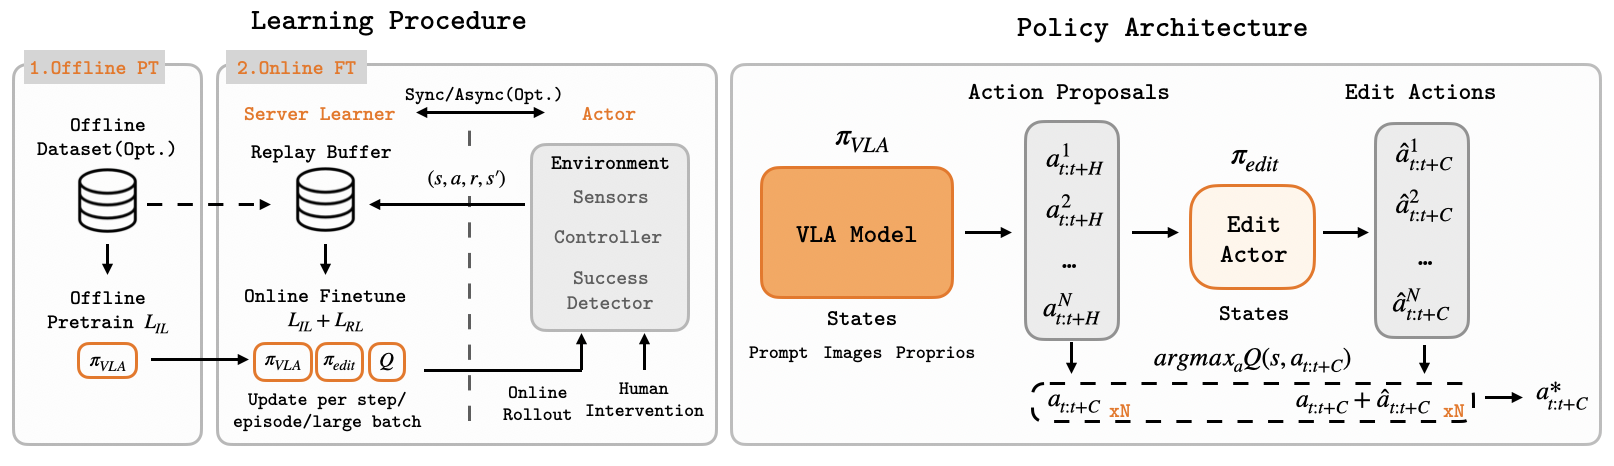
Presents a framework for reinforcement learning fine-tuning of real-time policies through decoupled slow action generation and fast, reactive editing, combining the reliability of RL with the reactiveness required for dynamic control.
Q-Learning With World Models figure

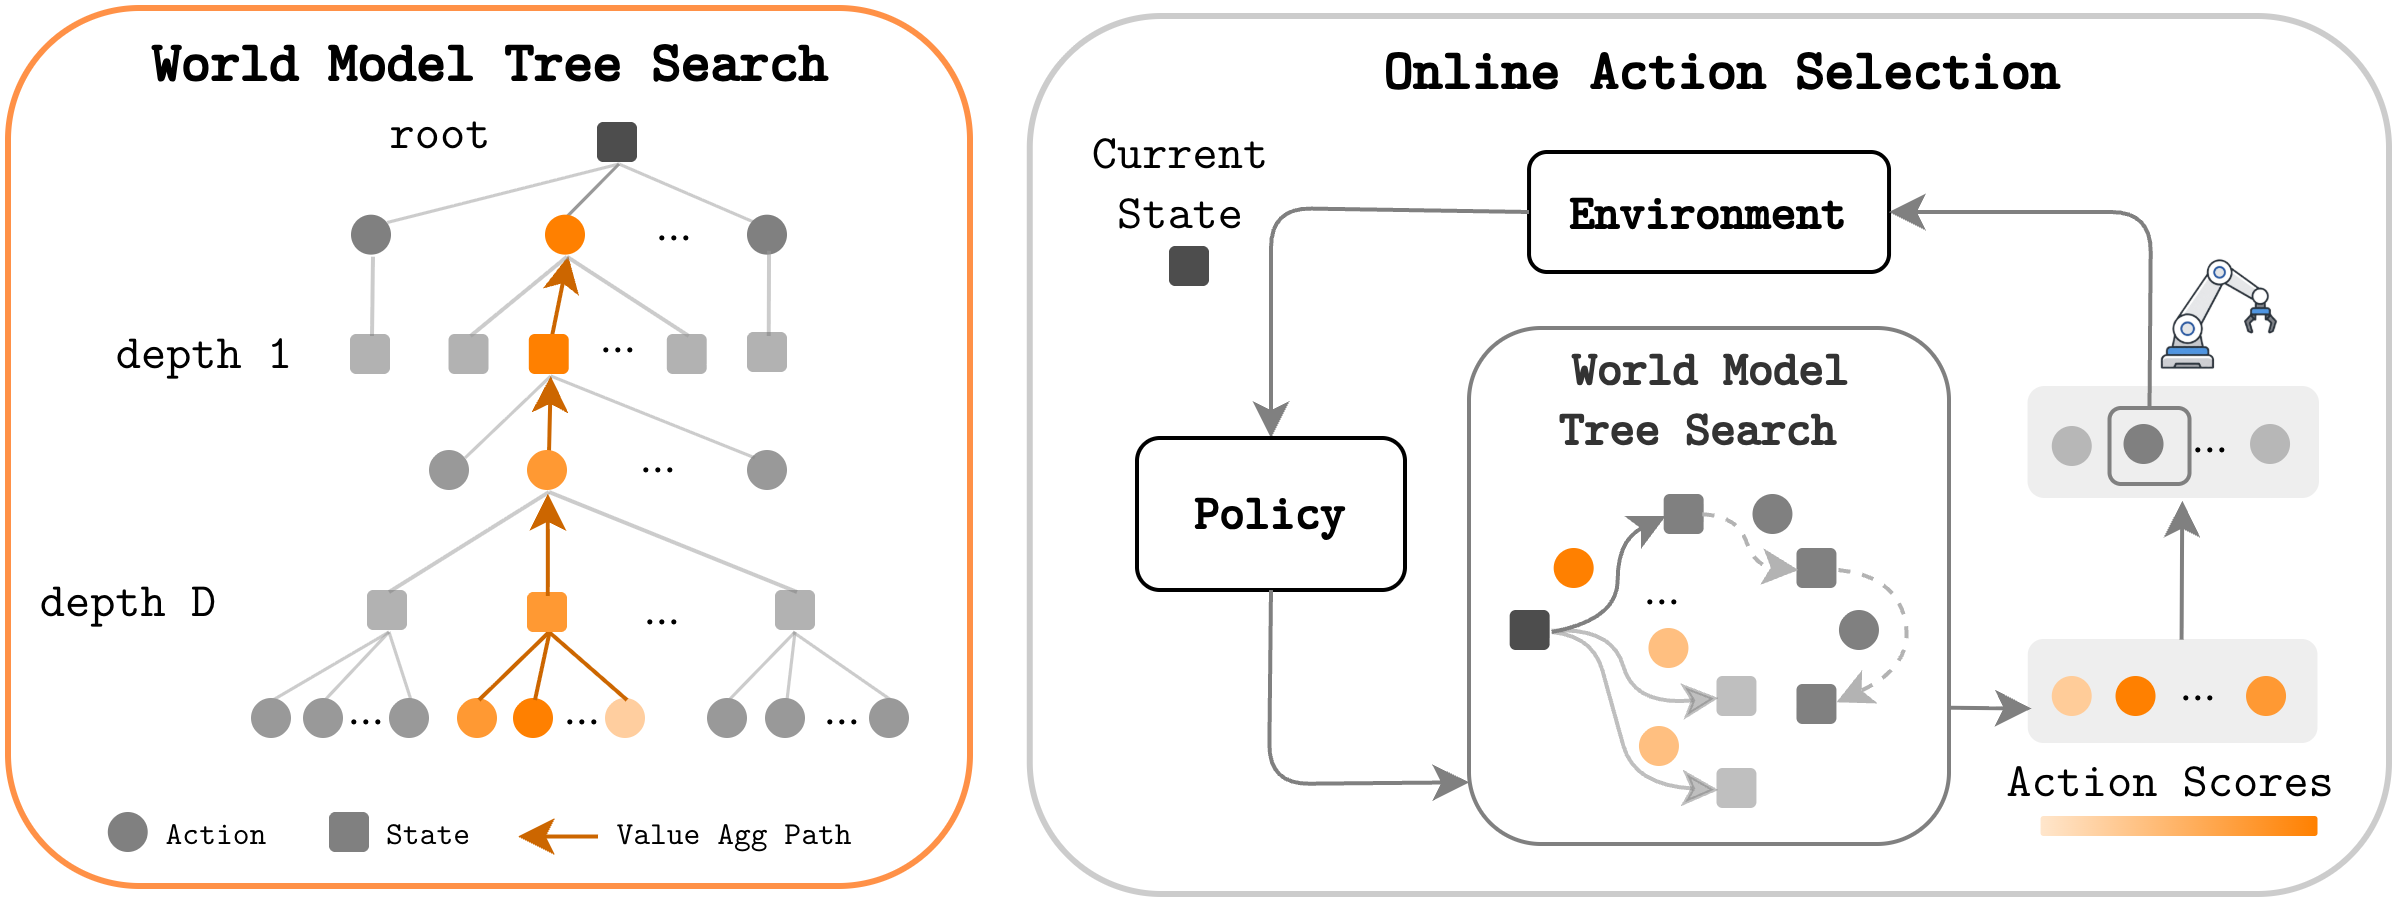
Q-Learning With World Models

P. Dong, Y. Jia, C. Finn, D. Sadigh

arXiv preprint arXiv:2608.17163, 2026

Proposes QWM, an approach for test-time scaling on top of standard Q-learning by using world models to imagine action outcomes and Q-function to evaluate and select the highest value actions for inference.

Do You Really Need to Pretrain Q-Functions for Online RL Fine-Tuning? figure

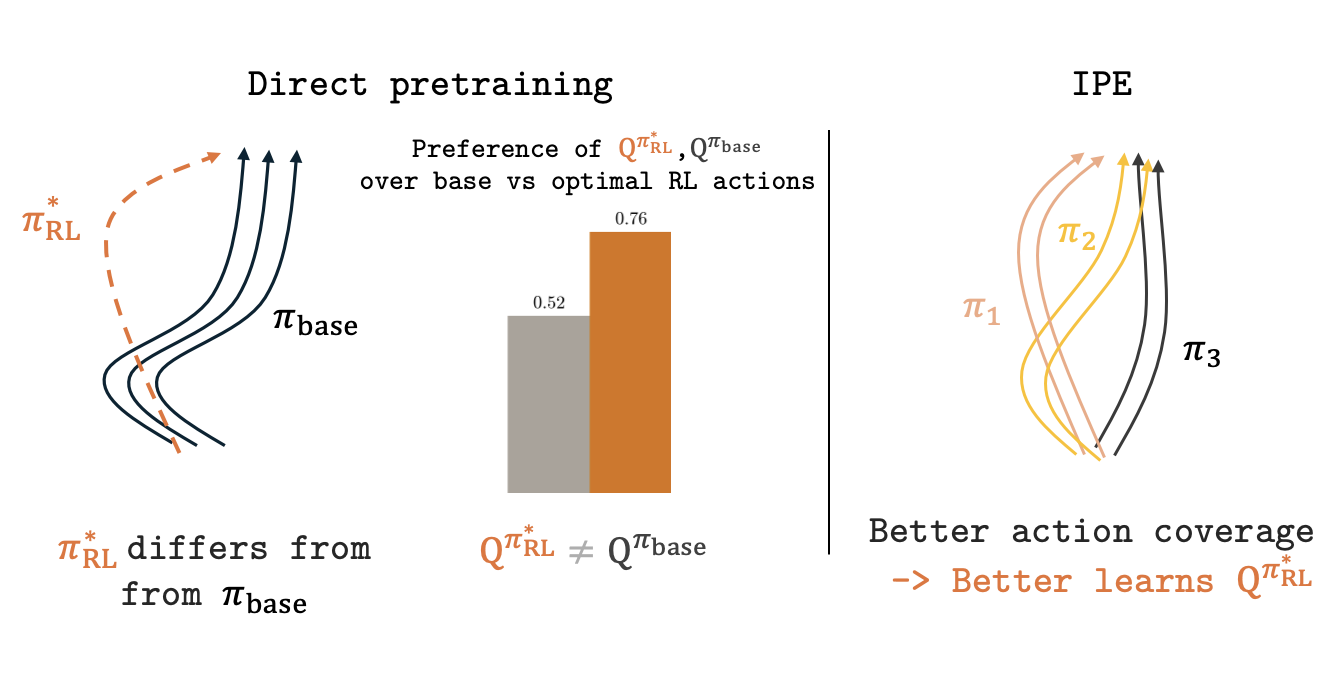
Do You Really Need to Pretrain Q-Functions for Online RL Fine-Tuning?

P. Dong, R. Polonsky, D. Sadigh, C. Finn

arXiv preprint arXiv:2607.27203, 2026

Shows that standard Q-function pretraining gives little benefit over random initialization, and introduces Initialization via Policy Ensemble (IPE), which bootstraps Q-learning from the pooled rollouts of several diverse pretrained policies for more effective online RL fine-tuning.

EXPO-FT figure

EXPO-FT: Sample-Efficient Reinforcement Learning Finetuning for Vision-Language-Action Models

P. Dong, K. Hung, T. Gao, D. Sadigh, C. Finn

Conference on Robot Learning (CoRL), 2026

Introduces EXPO-FT, a system for reliable, sample-efficient RL finetuning of pretrained vision-language-action models that reaches perfect task success across all evaluated manipulation tasks using an average of just 19.1 minutes of online robot data.

FASTER figure

FASTER: Value-Guided Sampling for Fast RL

P. Dong, A. Swerdlow, D. Sadigh, C. Finn

arXiv preprint arXiv:2604.19730, 2026

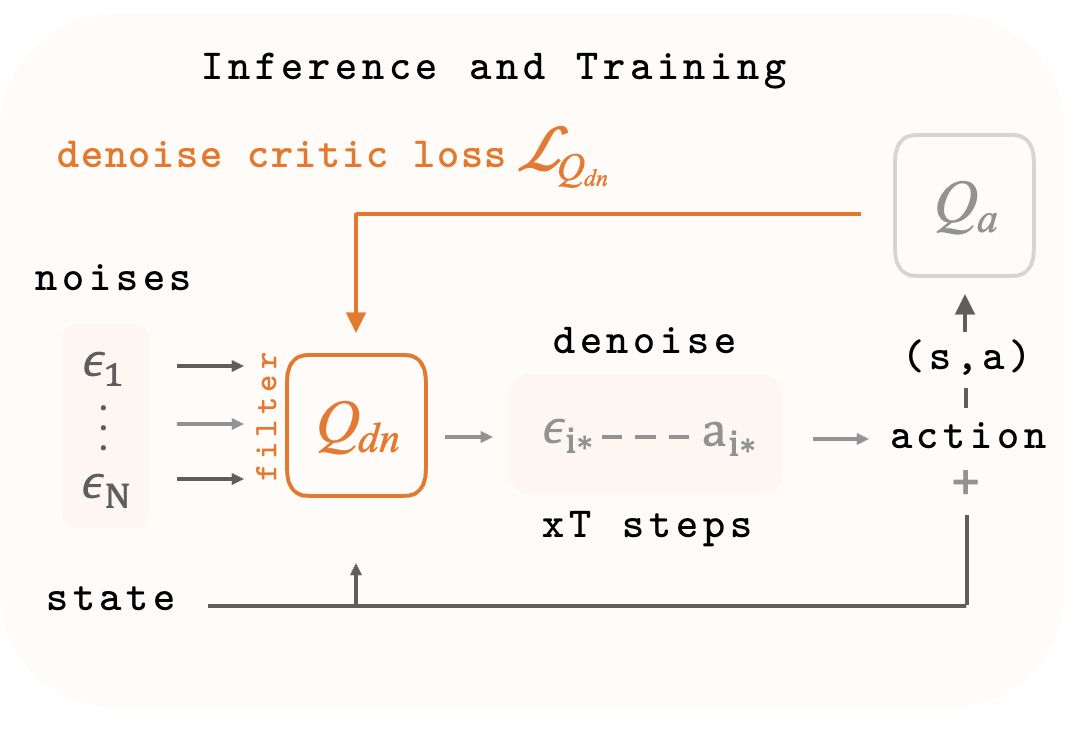
Presents FASTER, which models action-candidate denoising as an MDP and learns a value function in denoising space to filter candidates, recovering the benefits of test-time sampling in RL without its computational overhead.

Value Flows figure

Value Flows

P. Dong, C. Zheng, C. Finn, D. Sadigh, B. Eysenbach

International Conference on Learning Representations (ICLR), 2026

Uses flow matching to model the full continuous distribution over future returns in distributional RL, avoiding the discretization into bins or fixed quantiles required by prior categorical or quantile-based approaches.

EXPO figure

EXPO: Stable Reinforcement Learning with Expressive Policies

P. Dong, Q. Li, D. Sadigh, C. Finn

International Conference on Learning Representations (ICLR), 2026

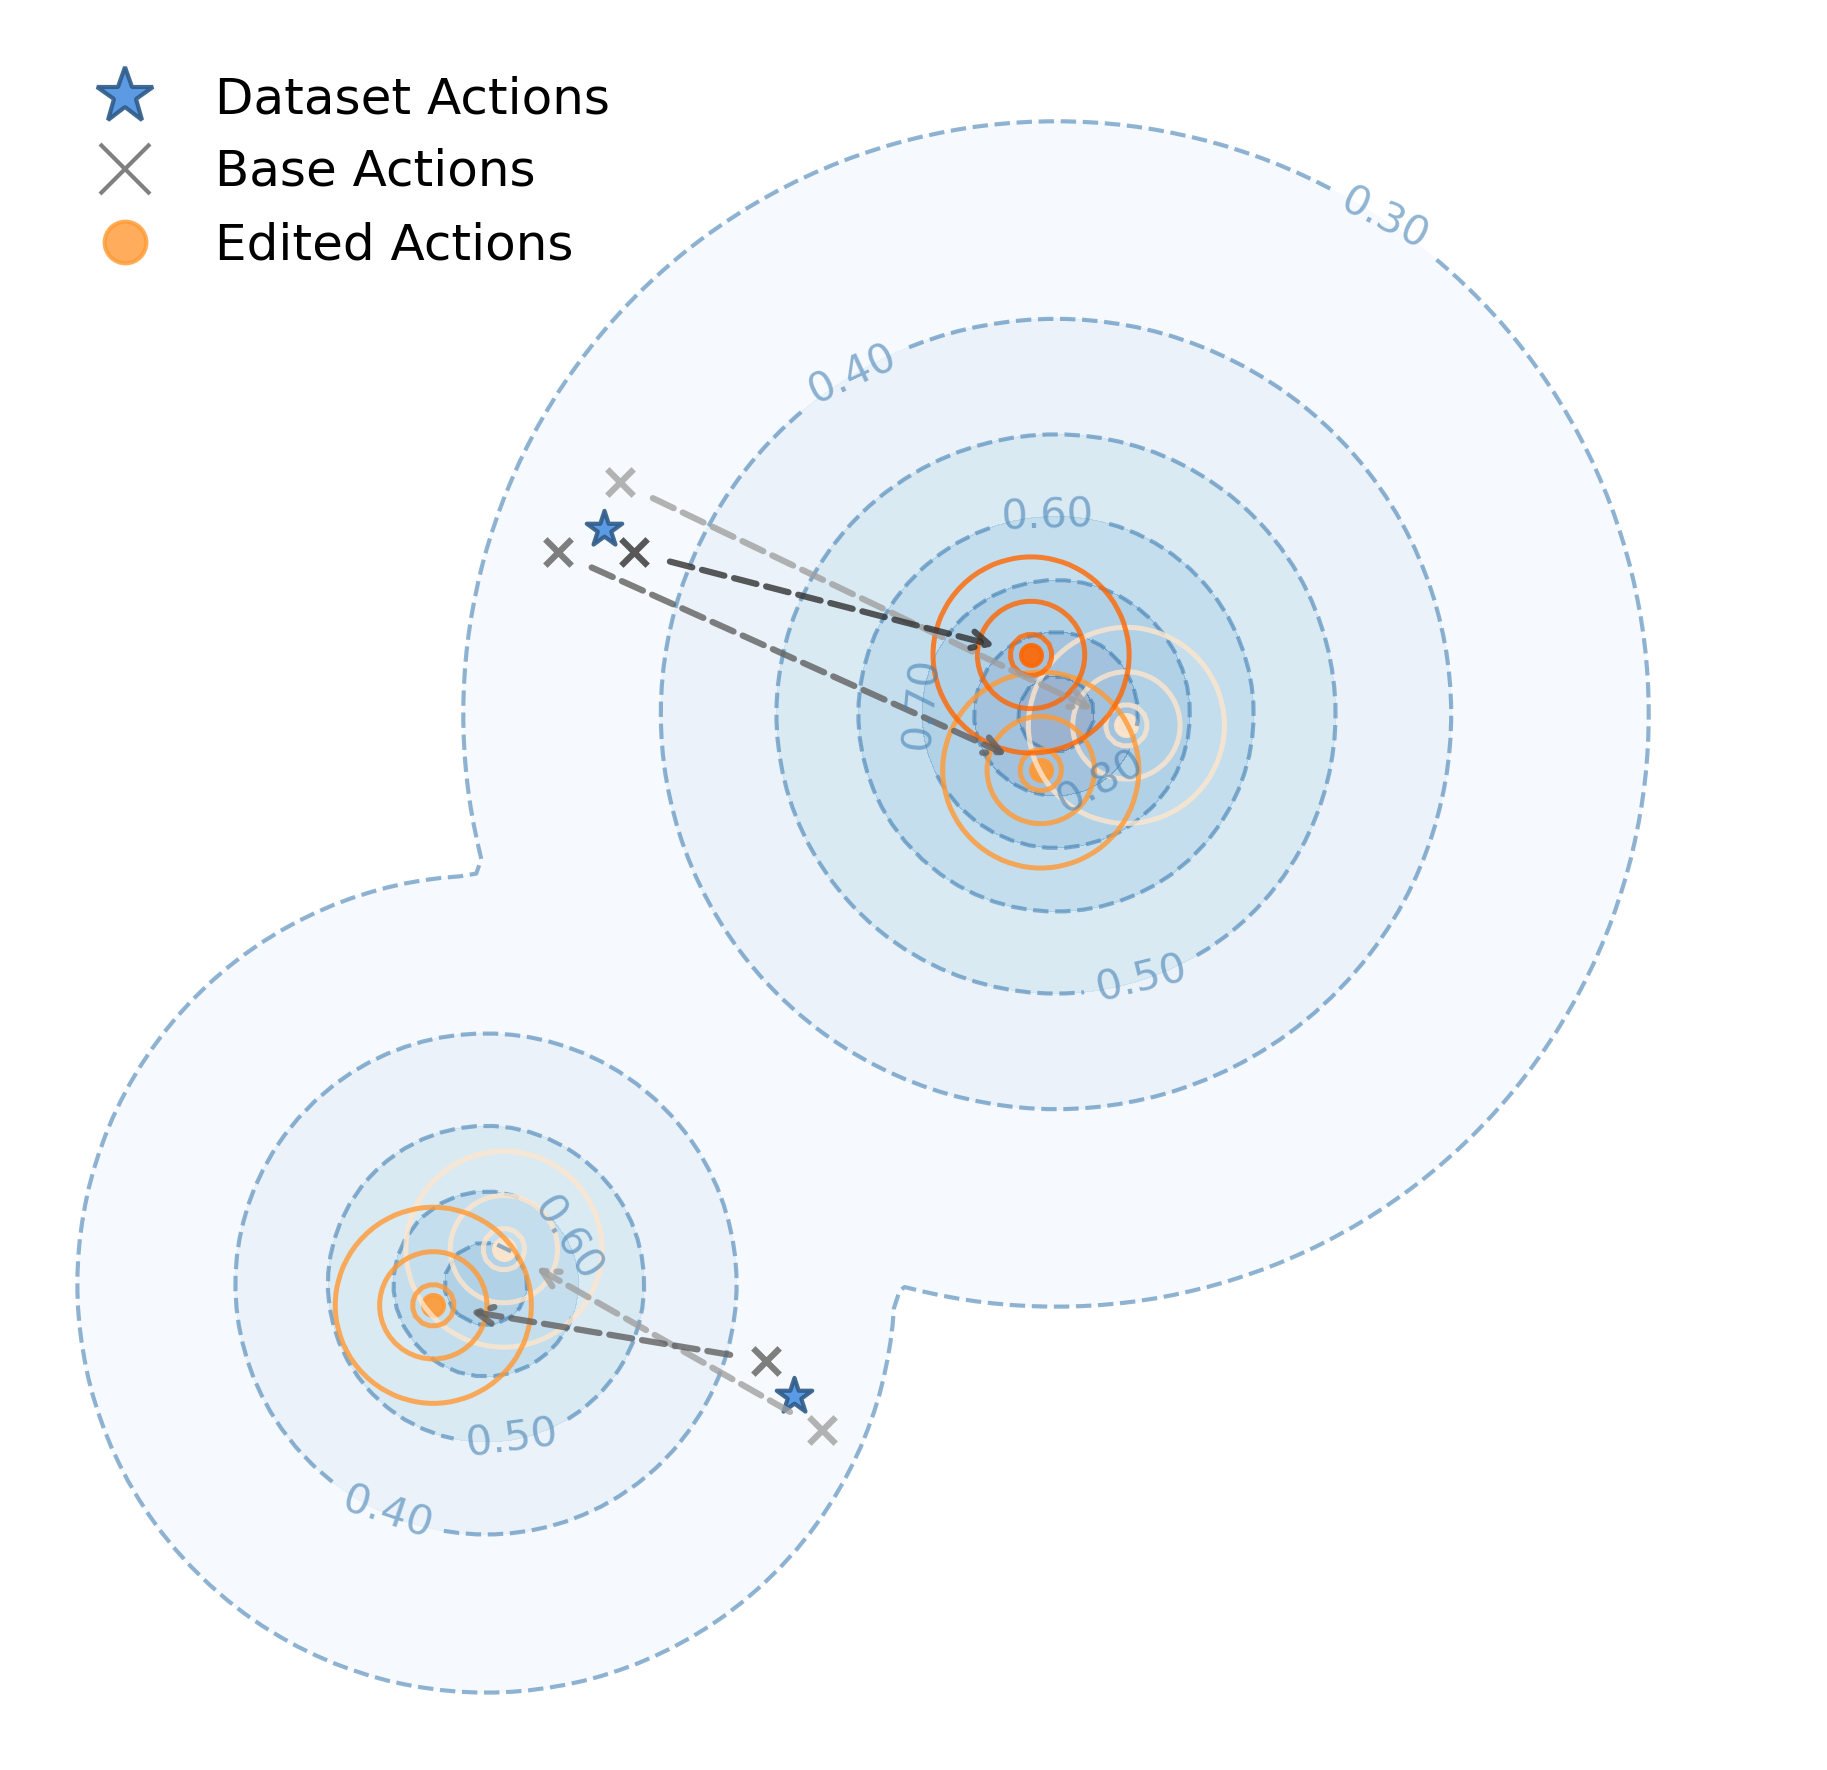
EXPO is a highly sample-efficient online RL algorithm for expressive policies that pairs a large expressive base policy trained via a stable imitation objective with a lightweight edit policy that shifts sampled actions toward higher-value regions for stable value maximization.

What Matters for Batch Online Reinforcement Learning in Robotics? figure

What Matters for Batch Online Reinforcement Learning in Robotics?

P. Dong, S. Mirchandani, D. Sadigh, C. Finn

International Conference on Learning Representations (ICLR), 2026

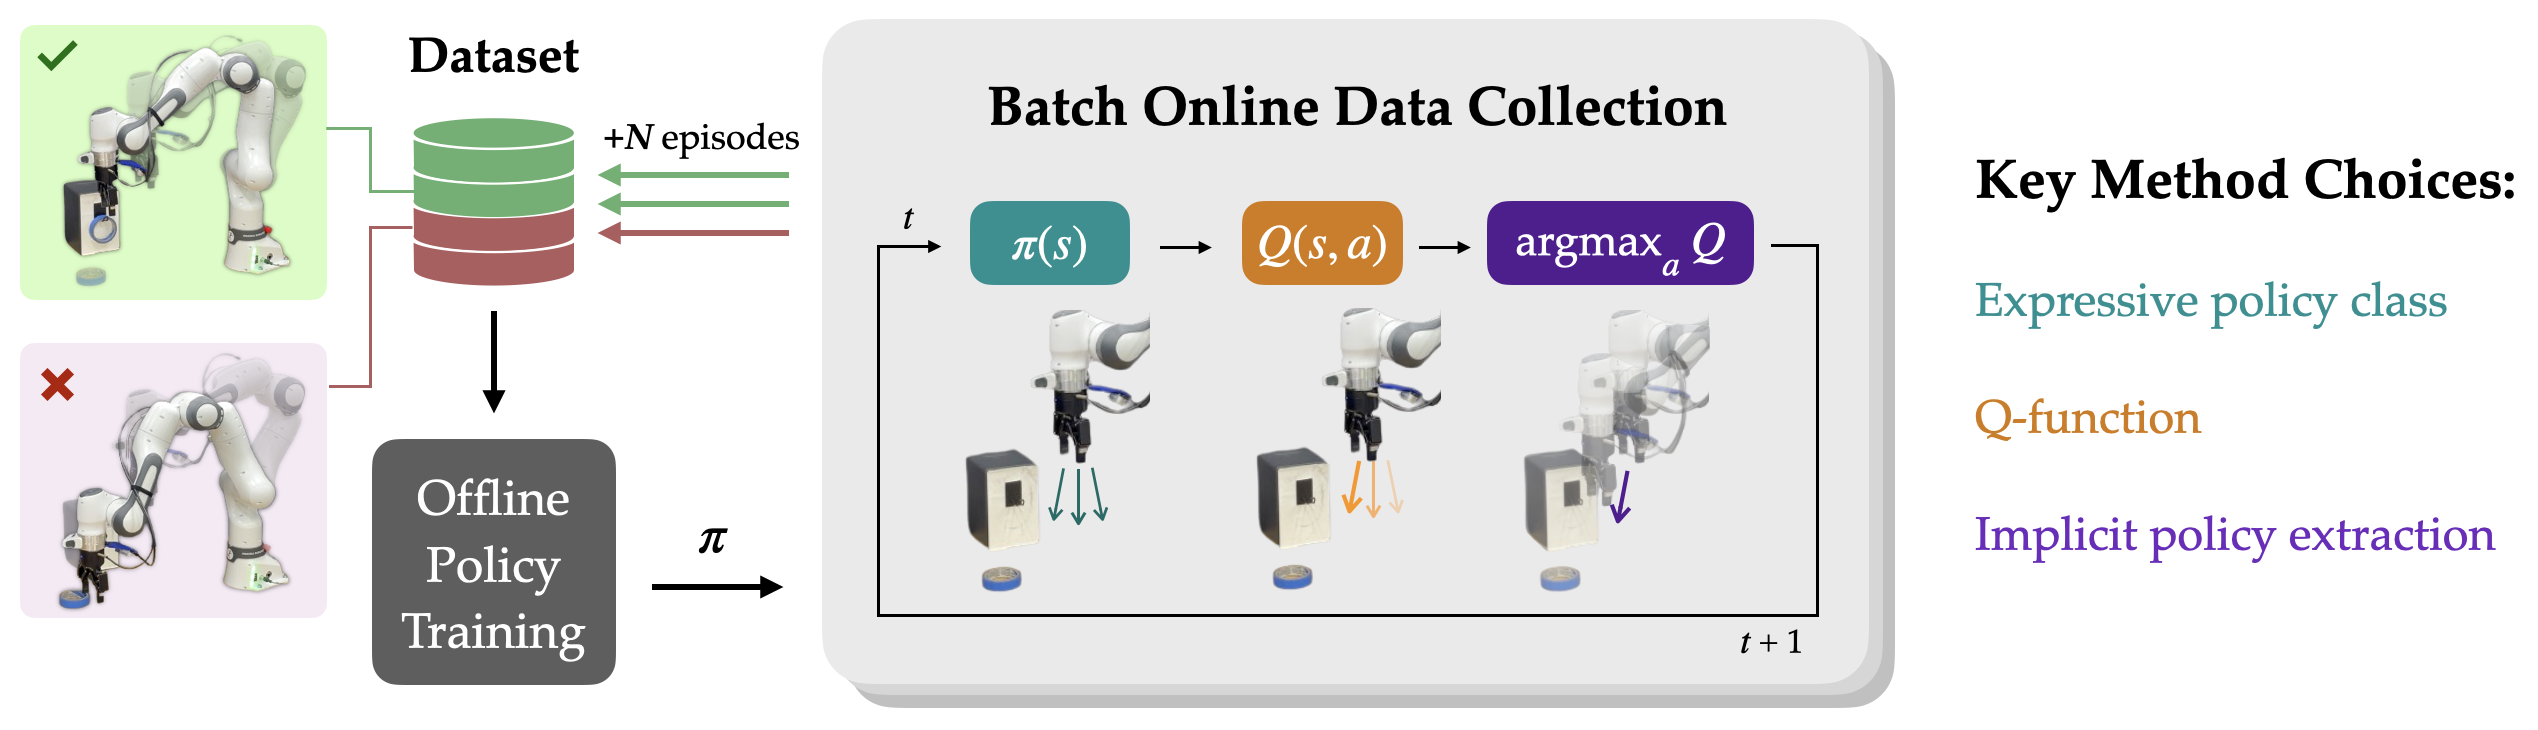
Conducts a systematic empirical study of the factors that make batch online RL — policy improvement from large batches of autonomously collected robot data — effective, addressing why prior imitation-learning-based approaches often fail to improve.

TQL figure

TQL: Scaling Q-Functions with Transformers by Preventing Attention Collapse

P. Dong, K. Hung, A. Swerdlow, D. Sadigh, C. Finn

International Conference on Machine Learning (ICML), 2026

Identifies attention-score collapse as the key failure mode preventing transformer value functions from scaling in RL, and proposes Transformer Q-Learning (TQL), which controls attention entropy to stabilize training as network size grows.

Posterior Behavioral Cloning figure

Posterior Behavioral Cloning: Pretraining BC Policies for Efficient RL Finetuning

A. Wagenmaker, P. Dong, R. Tsao, C. Finn, S. Levine

arXiv preprint arXiv:2512.16911, 2025

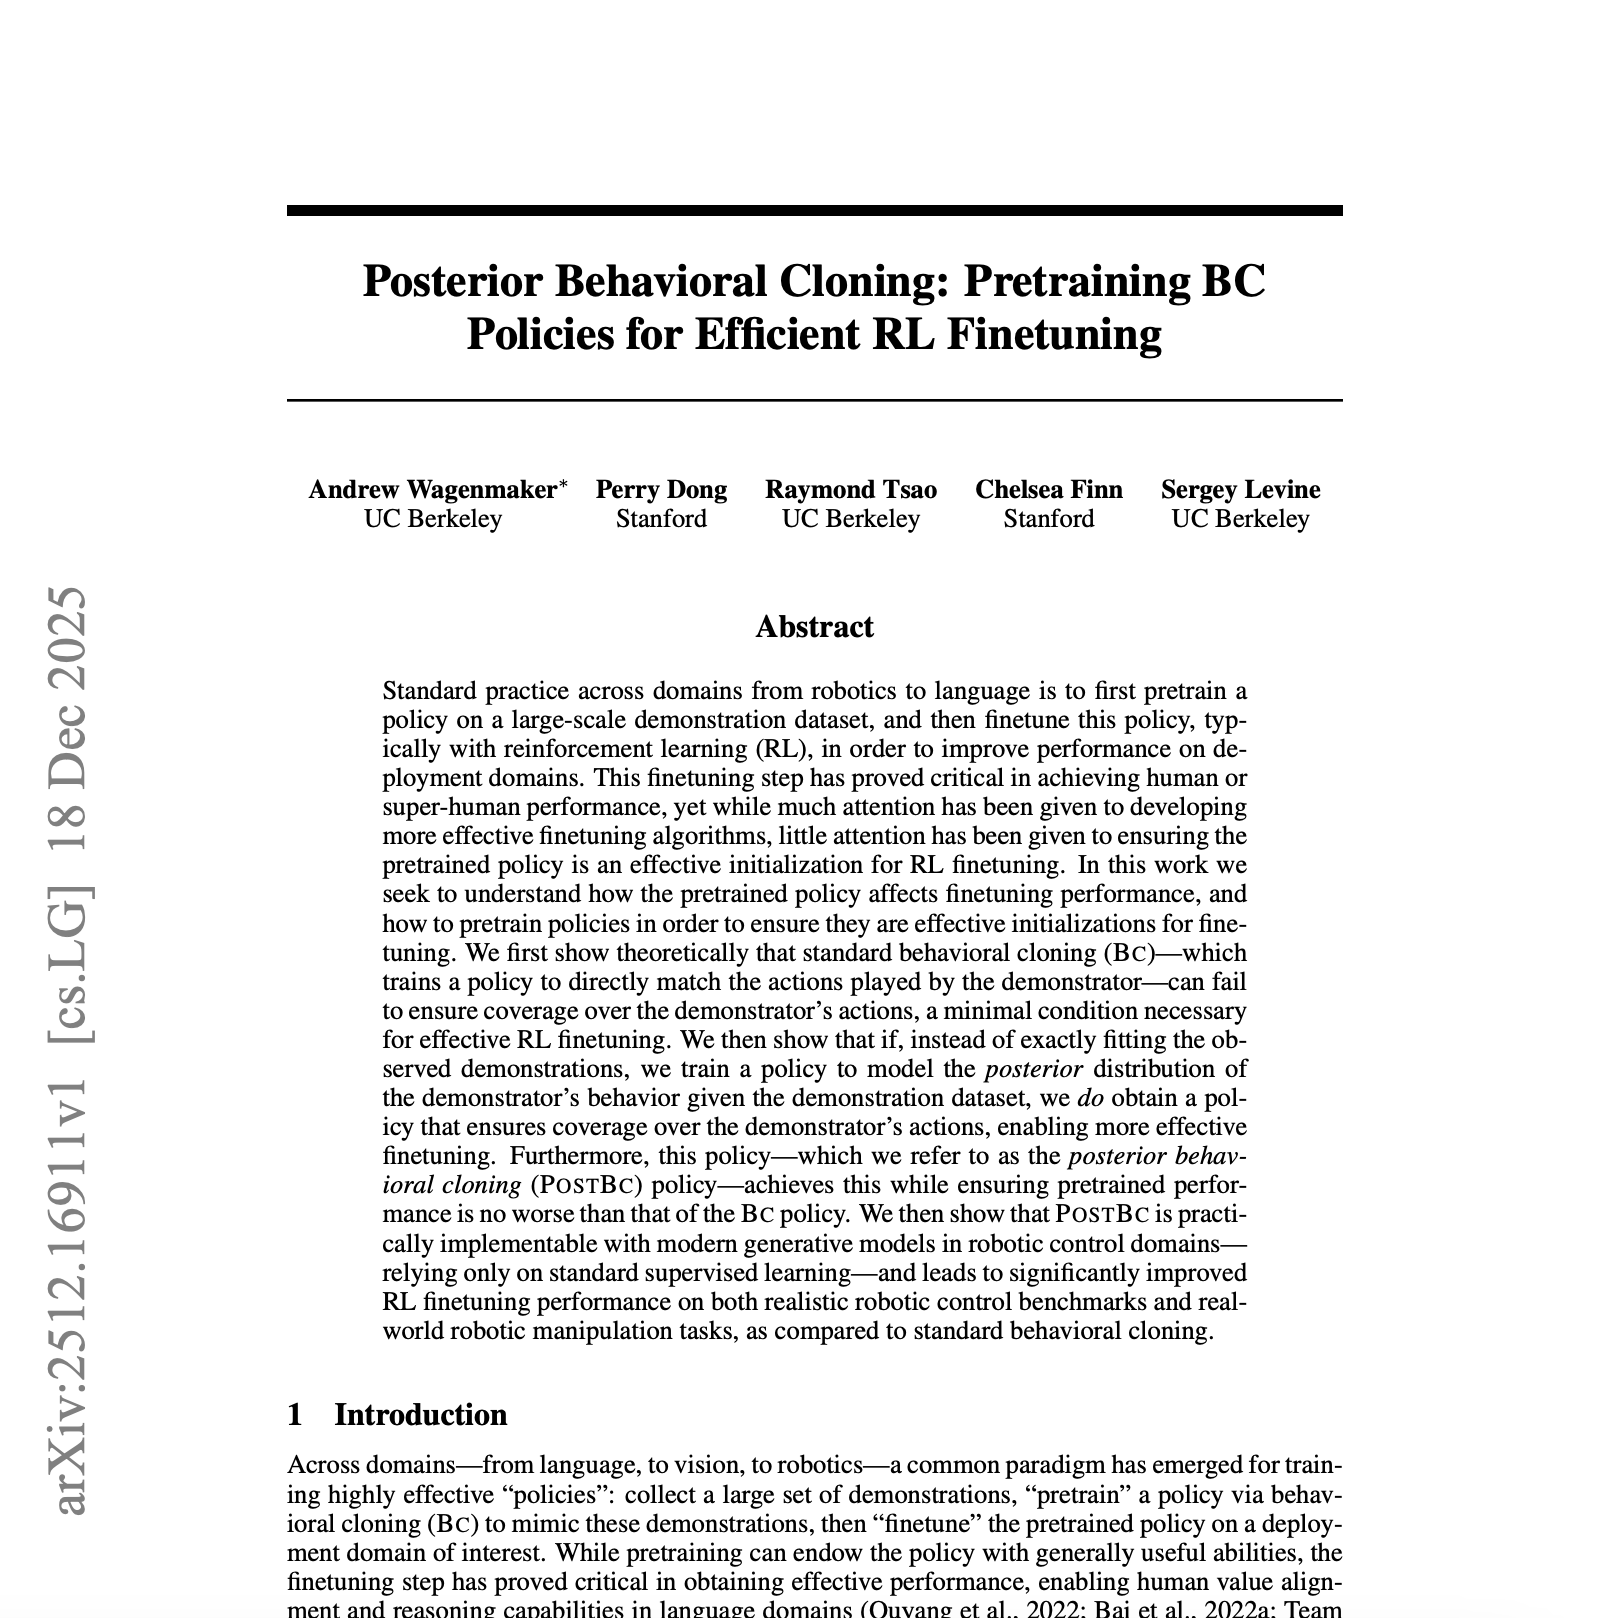
Shows that standard behavioral cloning can fail to cover the demonstrator's action distribution, and proposes Posterior Behavioral Cloning (PostBC), which models the posterior over demonstrator behavior to ensure coverage while matching BC's pretrained performance.

Reinforcement Learning via Implicit Imitation Guidance figure

Reinforcement Learning via Implicit Imitation Guidance

P. Dong, A. M. Lessing, A. S. Chen, C. Finn

arXiv preprint arXiv:2506.07505, 2025

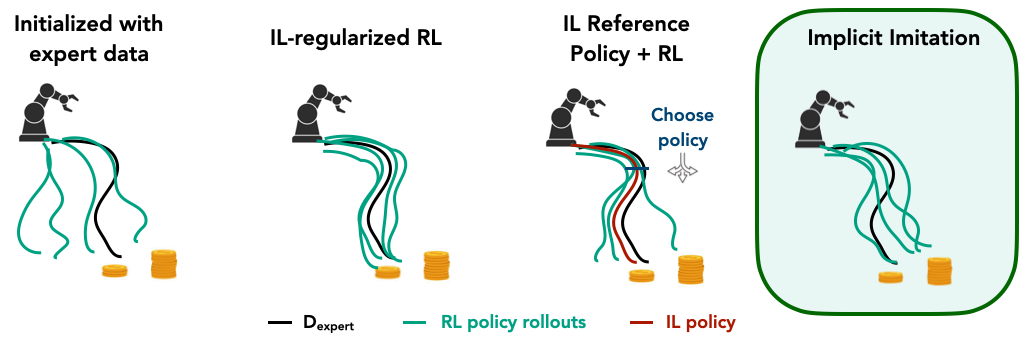
Introduces Data-Guided Noise (DGN), a sample-efficient RL method that uses prior demonstration data to guide exploration noise rather than explicitly cloning demonstrated actions, improving over prior RL-from-offline-data methods across continuous control tasks.

RLIF figure

RLIF: Interactive Imitation Learning as Reinforcement Learning

J. Luo, P. Dong, Y. Zhai, Y. Ma, S. Levine

International Conference on Learning Representations (ICLR), 2024

Proposes treating human intervention signals themselves as the RL reward in interactive imitation learning, in place of methods like DAgger that assume a near-optimal intervening expert, enabling policies that can surpass a suboptimal expert.